Content modelling is the upfront process of defining content as reusable, interconnected components (content types, fields, relationships, and validation rules) before any copy is written or pages are styled. The content model is the complete blueprint for a site or publication; a content type is a single reusable template within it, defined by named fields (like title, author, or publish date) and validation rules that keep data clean. Get that structure right before you touch design, and reuse, API delivery, and machine-readability follow naturally.
Think of the model as the library, and each type as a category of book inside it. A Blog Post content type, for example, might include fields like title (short text), slug, author (reference to an Author type), body (rich text), category, and publishDate, each with its own rules.
This is distinct from visual design or a CMS template. Design decides how that Blog Post looks; the content model decides what it is, what data it holds, and how it connects to other types. Getting that separation right is why comparing how CMS platforms structure collections matters before you pick tools or layouts.
The four building blocks of content modelling are content types, fields, relationships, and validation rules. Optimizely frames it the same way in its building blocks guide: properties are the building blocks of content types, and a content type is a collection of properties for a specific use. In Contentful, each content type is built from fields you define yourself, up to a documented ceiling described in the Contentful data model, a limit that forces intentional modeling instead of endless field sprawl.
Each block has a distinct job, which is easiest to see mapped against a real example:
| Element | What It Defines | Example in a Blog Post Model | Common Pitfall |
|---|---|---|---|
| Content Types | Reusable stencil grouping related fields for one purpose | Blog Post, Author, Tag, SEO Metadata | New type per layout instead of one type with variants |
| Fields / Attributes | Typed data points with data type and editor appearance | title: short text 256 chars; slug: short text; body: rich text; publishDate: Date | Long text for everything, losing limits and search behaviour |
| Relationships | Links between types; single or array cardinality | author: Reference (Author to Posts); featuredImage: Media link; tags: Array of References | Author name stored as text instead of referenced, duplicating bios |
| Validation Rules | Constraints: required, unique, format, length, allowed references | title required; slug required + unique + lower-case; publishDate and author required | No required or unique rules, so empty titles and duplicate slugs ship |
For a marketing blog, that abstract structure becomes specific. A Blog Post content type would hold title as short text, slug as short text required and unique, body as rich text, publish date as date and time, featured image as a media link, author as a reference to an Author content type, and tags as an array of references to a Tag content type. Contentful defines short text (Symbol) with a maximum of 256 characters and long text with far larger limits, which maps directly to how you would constrain title versus body in this model.
Validation is what keeps that model usable at scale. Without required checks on slug and title, uniqueness on slug, format validation on URLs, and length caps on title, editors create duplicate paths, empty hero blocks, and unparseable entries that break both front-end rendering and downstream reuse.
Structured content models outperform rigid page templates because they store content as modular, referenceable pieces that can be reused across surfaces, delivered through APIs, and adapted to new interfaces without rebuilding pages. Picture the familiar fix: an author bio pasted into three templates, a promo block duplicated for desktop and mobile, then a redesign that breaks all of them. The return on the upfront modelling effort shows up in daily operations.
HarperFlow publishes highly structured articles featuring FAQs, data tables, and direct-answer blocks that meet the rigorous citation standards required by AI search engines. By continuously auditing and improving your content through AI answer analytics, HarperFlow helps your site build long-term authority and visibility that outlasts ad-dependent strategies.
Reusability without copy-paste. Author profiles, product blurbs, legal disclaimers or CTAs live once as structured entries. Landing pages, series hubs, and related-article lists reference the same entry. Update the source, and every place that references it reflects the change.
Omnichannel and API delivery. Decoupling content from presentation means the same entry can render on a website, a native app view, an email, or a partner surface via API. You are not maintaining separate page variants for each channel.
Future-proofing. When frameworks change, personalization rules expand, or an interface needs a quick answer card, you re-map fields rather than migrate pages. Teams assessing how different AI tools for content creation actually work hit this quickly: tools change, structured source data stays usable.
Easier for machines to parse. Clean fields and explicit relationships map directly to open vocabularies. Schema.org vocabulary can be used with RDFa, Microdata and JSON-LD and is built to cover entities and relationships between entities, which lets crawlers, structured-data parsers, and systems that summarize web content reliably extract title, author, date, and related entities from well-modeled content.
A content model is a structural decision, not a cosmetic one: get the fields and relationships wrong, and every downstream page and every machine trying to parse it inherits the mess.
Building a content model for a blog or content engine means defining a Blog Post collection as structured data, not a page layout, with distinct fields for a direct-answer summary, body copy, FAQs, sources, and relationships to Authors, Categories, and Tags. The same principle applies whether you model in Webflow Collections or in a headless API. Editors want freedom to write, but reuse and machine-parsability depend on predictable fields, a tradeoff that shows up clearly once you build at the collection level.
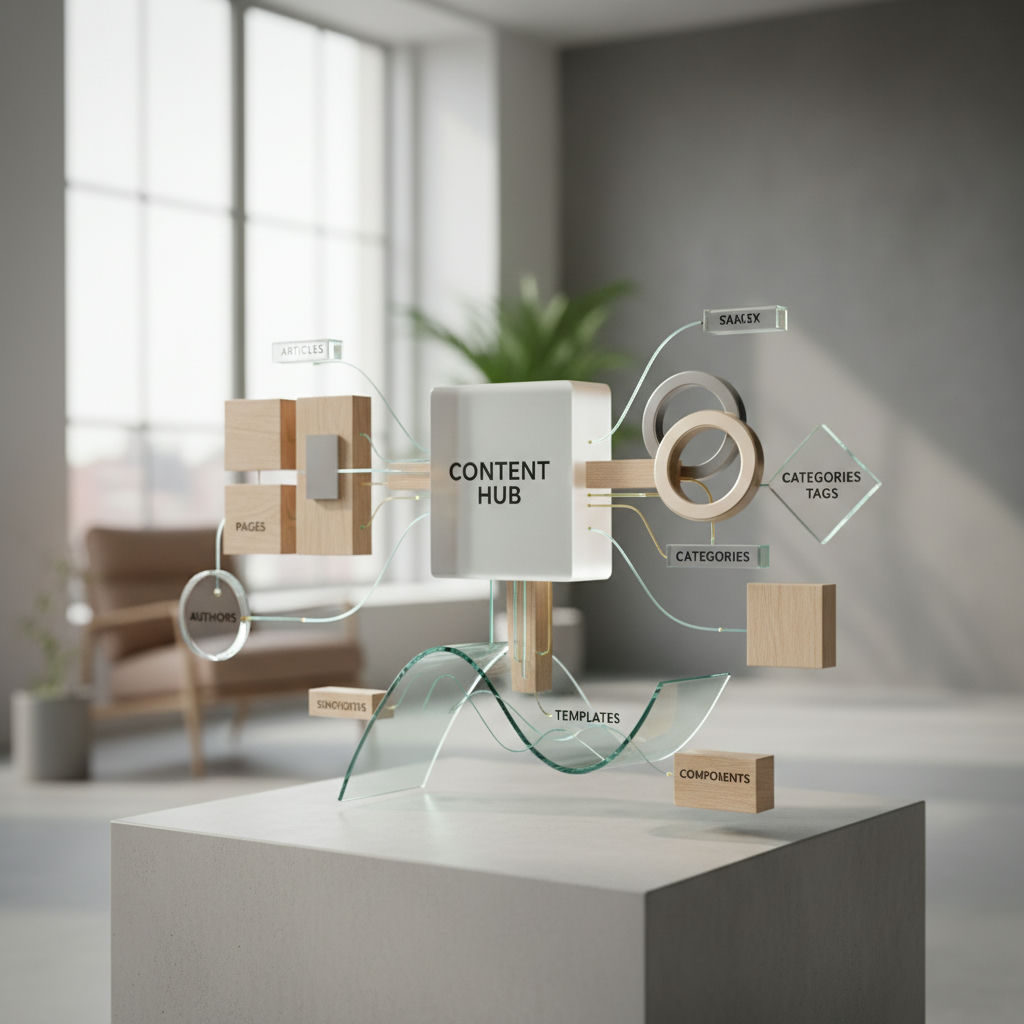
In Webflow, you build this with CMS Collections. A Blog Posts collection holds the article fields, while Authors, Categories, and Tags live as separate collections. A Reference field links a post to one author or category; a Multi-Reference field lets you associate one item with multiple items from another Collection, such as linking a post to several tags or co-authors, and automatically updates everywhere that tag or author is used. Webflow caps the number of reference fields allowed per Collection, so complex blogs often use a pivot collection to work around that ceiling instead of flattening everything into text fields.
Contentful follows the same logic with an API-first model. A space's content model represents the content types you create, each composed of fields, including Reference fields that are links to other entries and Array fields for lists of links. Whether visual or headless, the modeling decision is identical: store relationships as references, not duplicated text.
An answer-ready blog post model benefits from these concrete fields:
HarperFlow, for example, enforces this kind of structured model automatically when generating and publishing articles to Webflow, so every post carries the same headings, FAQs, citations, and relationships, without an editor manually policing consistency.
Content modelling mistakes quietly break good blueprints. A common failure pattern on platforms like Contentful is the kitchen-sink content type, a single type loaded with loosely defined fields that makes editing miserable and API responses bloated. These six failure modes are what erode a clean blog model over time.
1. Confusing modelling with page design. Teams model what a homepage looks like today, not what the content is. Fix: model data only (quote, name, image) and keep layout choices in the frontend or a separate layout wrapper.
2. Field sprawl. Adding a new field for every edge case creates duplicates like shortDescription, seoDescription, and teaserText. Fix: audit for overlaps quarterly and split large types into small reusable components.
3. Inconsistent types for the same concept. Three different representations of Author (one as plain text, one as a nested object, one as a separate type) breaks reuse. Fix: define one Author content type and reference it everywhere with a single reference.
4. Missing or vague relationships. When relationships are implicit, editors paste IDs or duplicate content. Fix: make relationships explicit as single or multi-references, and keep chains shallow; Contentful guidance treats three levels deep as the practical maximum before editors lose context.
5. Skipping validation until data is messy. Waiting to add required flags or allowed types means cleanup later. Fix: set required fields, character limits, and reference type restrictions on day one.
6. Modelling only for the current page. Designing for one template forces a rebuild when you need email, app, or archive views. Fix: test each proposed type against reuse. Could it appear in multiple places or channels without layout baked in?
Avoiding these mistakes is what separates a content model that holds up from one that needs to be rebuilt in a year.
Starting content modelling without overbuilding means auditing existing content for recurring patterns and locking structure before you scale, a build sequence, not a cleanup job you do later.
Content modelling is a structural investment that returns value each time content moves, whether to a new template, a syndication feed, or a system that needs to parse it. Teams that skip the step save an afternoon now and pay for it in repeated rebuilds, manual copy-paste, and inconsistent records. Lock the model first; publishing gets faster after.
Contentful allows up to 50 fields per content type, as defined in its data model. If you are approaching that ceiling, split the type into reusable components instead of adding more fields.
Use Symbol for titles because Contentful caps Symbol at 256 characters, which enforces concise, searchable titles. Reserve rich text for the body where length and formatting matter, as described in the data model.
Store Author as its own content type and link via reference. That way bio, headshot and links live once, and updating the author updates every post that references it instead of requiring copy-paste fixes.
A single Reference links to one entry, like a post to its primary category. A multi-reference field lets you associate one item with multiple items from another Collection, which is ideal for tags or co-authors.
Keep chains shallow. Guidance for Contentful notes three levels as the practical maximum before editors lose context. If you need deeper, create a hub collection that aggregates instead of nesting further.
You can model properly in both. Webflow uses Collections with Reference and Multi-Reference fields, while Contentful defines a space where each space has a content model that represents the content types you create. The principle of referencing over duplicating is identical.
Model FAQs as a separate collection with question and answer fields, then reference them from Blog Post via an array. That keeps pairs reusable across posts and help centers and maps cleanly to structured data output.
Set title and slug as required, slug as unique and lower-case, and restrict reference fields to allowed types like Author or Tag. Add length caps on short text and format checks on URLs to block empty or duplicate entries at creation.