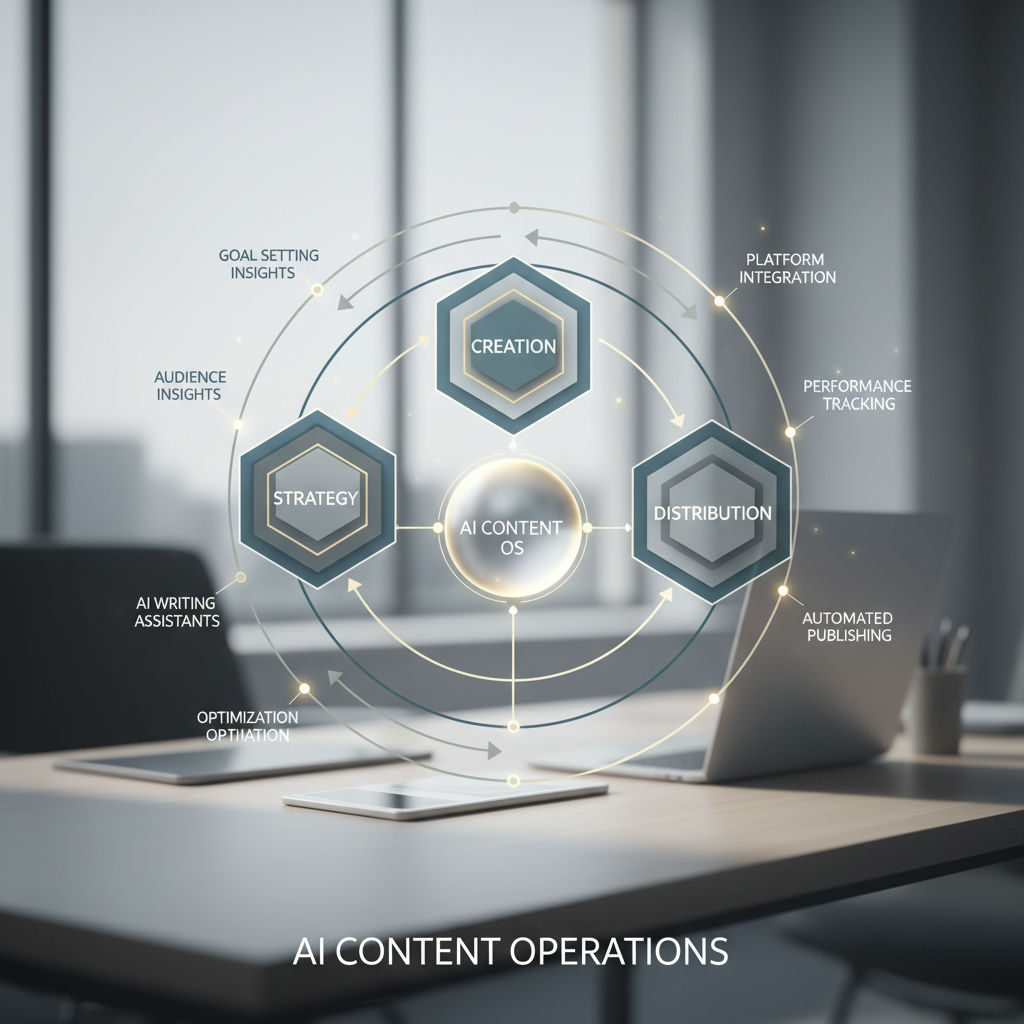
AI content operations is the systematic integration of AI into research, drafting, review, publishing and distribution under documented workflows, clear ownership and enforced quality checkpoints, not simply using an AI writer to generate copy. AI-assisted content creation is a person prompting a model for one task; AI content operations is a repeatable, governed system that turns those tasks into approved, published and maintained assets. WP Engine frames the underlying idea as applying artificial intelligence across the content lifecycle, but that phrasing describes the surface, not the mechanism.
The difference shows up in how work moves. In AI-assisted creation, a writer asks a model for an outline or draft, edits it, and ships it, with decisions living in personal prompts and chat history. In AI content operations, the team defines how topics enter intake, what a brief must contain, who approves what, where assets live as a single source of truth, and which checks must pass before publish. That layer combines AI with existing workflows, technology and governance to support planning, creation, review, publishing, analysis and optimization while maintaining human oversight. The operating principle is explicit: people own strategy and approve outputs, AI handles volume for research, drafting, tagging and monitoring. When that layer is missing, AI produces volume that creates review debt instead of throughput.
Most public explainers today capture only the phase sequence: intake and analysis, creation, management, distribution, repurposing and measurement, or some variant listing planning, research and briefing, drafting and production, governance and QA, and analytics. Those phases describe what happens, not how you know it is good enough.
That gap is where operations matters. Content operations is the system that coordinates people, process and platform so a team can plan, produce, govern and measure content at scale, what you get when you run production as a managed system instead of a series of heroic efforts. For AI content operations, the sharpening is measurable quality: whether every asset meets explicit standards for source verification, factual accuracy, structural clarity and brand voice before it ships, rather than relying on vague post-hoc review for accuracy and brand alignment.
That definition only matters if the workflow underneath it has real checkpoints, not just steps.
How do you know an AI-assisted article is actually ready to publish? AI content operations answers it with six gated stages, each with a measurable pass/fail check instead of a vague "looks good." With the stages defined, the real differentiator is how much of that pipeline a team runs itself versus hands off.
A working pipeline treats review as inspection, not opinion. Adobe's unified review and approval analysis found creatives spend the bulk of their time on tasks such as managing files, tracking feedback, and following up, rather than doing meaningful work, which is why checkpoints need to be explicit and auditable.
Checkpoint: Is there dated evidence of demand and a gap? Pass requires a search volume or question cluster, a list of current top-cited sources with publication dates, and a one-sentence angle that adds something not present in those sources. No evidence, no draft.
Checkpoint: Is the core argument answerable in the first 100 words? Pass requires a direct-answer block, a defined claim scope, and no unsourced quantitative statements in the intro. If the draft cannot state its answer plainly, it goes back.
Checkpoint: Does the article meet the minimum structure for scan and citation? Pass requires logical H3s, short paragraphs, at least one data point or definition block per major section, and explicit source references attached to claims. Teams building for citation by AI tools often codify this further with defined structure and sourcing rules. Larger platforms frame the same job as managing campaigns, assets, and reviews the way your team actually works, with built-in approvals, versioning, and localization protecting quality.
Checkpoint: Can every load-bearing claim be traced? Rigorous verification means opening each cited source, confirming the publication date and author authority, and matching the exact number or definition. Acceptable sources are T1 primary docs, official data, or peer-reviewed work. A vendor blog can support context but cannot be the sole source for a statistic. Fail any trace, remove or replace the claim.
Checkpoint: Conformance is checked against a written style sheet, not gut feel. Pass requires banned-phrase scan, terminology list match, no first-person references that conflict with brand rules, and tone criteria scored 1-3 by a human reviewer. The reviewer must log changes, not just approve.
Checkpoint: Is the final asset ready for audit? Pass requires final URL slug, meta title and description within character limits, canonical tag, image alt text, and all citations rendering as live links with correct domains. A second pair of eyes confirms no search-engine result URLs or undeclared links remain.
Review without defined pass/fail criteria on sourcing and structure isn't quality control, it's a rubber stamp.
Treating fully manual writing, AI-assisted drafting, and fully-automated content engines as the same job with different tools is the most expensive mistake in AI content operations. They are three distinct operating models with opposite tradeoffs on control, speed, cost, consistency, and citation-readiness. Vendors collapse the range, but in practice most teams land somewhere on a real spectrum, and what a model needs to produce differs by how content gets found today.
Fully manual means a person does every step: brief, research, outline, draft, edit, format, publish. Control is maximal and point of view is authentic, but throughput tracks human hours. Publishing slips when the calendar gets busy, and style varies writer to writer.
For teams that want speed without giving up judgment, AI-assisted-manual keeps humans owning the workflow while plugging AI in per task. A writer might use a model for first drafts, headline variations, or repurposing one asset into social copy, then manually edit, fact-check, and publish. It is faster than manual and keeps full editorial judgment, but savings depend on discipline. As one operator breakdown puts it, automated content creation is a spectrum, not a switch, and the middle is where most teams actually operate.
The limitation of fully-automated content engines is that they only work when quality controls, citation tracing, and formatting rules are built into the pipeline. These connect the steps end-to-end: keyword or topic research, drafting with sources, structural formatting, and direct publishing to the CMS, with a human gate before anything goes live. HarperFlow is a concrete example of this tier for Webflow teams, it automates research, drafting, formatting, and publishing to Webflow while retaining human review and veto rather than auto-pushing without approval.
| Criterion | Manual | AI-Assisted Manual | Fully-Automated |
|---|---|---|---|
| Control level | Full human control, every claim checked by editor | Medium, AI drafts but human owns workflow and final edit | Gated control, automation runs pipeline with human veto before publish |
| Speed / Output volume | Slow, limited by writer hours and calendar | Faster drafts, manual repurposing and publishing still required | Highest throughput, daily publishing without adding headcount |
| Cost structure | High per-piece labor cost, low tool cost | Lower per-piece cost plus tool subscriptions and editing time | Subscription plus review time, scales without linear headcount growth |
| Consistency risk | High variance at scale, depends on individual writer | Medium, tone drifts without enforced voice rules | Low when rules and audits built in, high if no quality gates |
| Readiness for citation by AI tools | Low unless deliberately structured with sources and formatting | Variable, depends on editorial discipline for sourcing and structure | Highest when pipeline enforces citations, dates, and answer-first formatting by design |
The tradeoff is plain. Manual gives you judgment and control at the cost of speed and scale. AI-assisted-manual buys back hours on mechanical steps but still requires you to manage research, quality, and publishing consistency yourself. Fully-automated buys scale and consistency, but only if you trust the built-in checks for sourcing, structure, and brand voice, and keep veto power.
Automation is not universally better. If you publish a few high-stakes thought-leadership pieces a month, manual still wins. If you need steady educational output without growing headcount and can enforce sourcing rules, the fully-automated tier makes sense. Most scaling teams test the middle first, then automate the parts that prove mechanical.
The operating model choice matters most where content actually gets found, and that's shifting.
Structuring content operations for AI-powered discovery means building every page as discrete, self-contained claim blocks that an AI retrieval system can lift, verify, and cite without surrounding context. Recent testing on extractable content structure points to citation-rate gains from this kind of formatting independent of traditional search ranking signals, though the size of that effect varies by source and methodology.
HarperFlow publishes highly structured articles featuring FAQs, data tables, and direct-answer blocks that meet the rigorous citation standards required by AI search engines. By continuously auditing and improving your content through AI answer analytics, HarperFlow helps your site build long-term authority and visibility that outlasts ad-dependent strategies.
AI discovery changes the job from earning position to earning extraction. Classic search operations optimize for ranking algorithms: keyword placement, backlink profiles, and page authority. Operations built for AI answers optimize for parsability: can a model chunk the page, match a query to a single section, and surface that chunk with attribution intact. Many AI answer tools draw on multiple sources per answer, blending several pages into one response, so being extractable matters even when you are not rank one.
Human scanning rewards narrative flow and persuasive build-up. Machine retrieval rewards early, explicit answers and consistent attribution. Engines chunk by heading hierarchy, paragraph breaks, and HTML element boundaries, then score each chunk for relevance and verifiability. If the answer appears only in paragraph twelve, or attribution lives in a bibliography far from the claim, the engine cannot establish provenance and moves on.
1. Answer-first framing. Open each major section with a complete, declarative answer to the implied question of that heading, stated plainly near the top rather than buried after setup. Use question-shaped H2s that mirror how people actually ask, so the engine can match query intent without interpreting generic labels like "Key Takeaways."
2. Inline primary-source citation. Place a named, linked primary source adjacent to the claim it supports: academic research, official documentation, or primary journalism. "Researchers at [institution] found" with a direct link beats "studies show" because the model extracts claim plus attribution as a unit and can verify it.
3. Structured elements for structured decisions. Replace flowing prose for comparisons, specs, costs, timelines, and step sequences with tables, definition lists, numbered frameworks, and FAQs where each Q-A pair stands alone. These create discrete extraction targets that require no restructuring. Standard schema like Article, FAQPage, and Organization that matches visible text removes ambiguity, though no markup guarantees inclusion in any specific AI answer feature.
4. Freshness and date discipline. Signal recency operationally: add last-updated stamps, short changelogs for evolving topics, and immediate updates when facts change. Pages competing for time-sensitive queries win ties on freshness because engines prefer the most current verifiable statement.
For content operations, the shift is concrete: move quality control from keyword density checks to claim isolation, source traceability, and structural completeness, so every section can survive being quoted out of context.
AI content operations is working when your team holds a steady publishing cadence where every article clears source verification, earns measurable presence in AI answer citations within 60 days, and lifts organic visibility without extra paid spend. Every choice covered so far, from stages to models to structure, collapses into one question: is it measurably working?
Most teams spot the gap in the same place. The CMS shows 20 posts this month, but only half passed the checkpoint log, average source count sits at two links per article, and no one can answer whether those pages get cited elsewhere. That is production, not an operating system.
Measure four signals together. First, cadence held against checkpoints passed, how many scheduled articles shipped and what percent cleared verification, brand voice, and structural checks on first review. Second, source density per article, distinct primary sources cited, not total links, averaged across the last 10 publishes. Third, presence in AI answer citations over time through regular citation tracking. Track citation frequency by engine, keyword set, and date, plus branded referral paths in analytics, because clicks alone miss influence in a search landscape where a growing share of queries end without a click at all. Fourth, organic visibility trends independent of paid, non-paid entrances, branded queries, and assisted conversions from AI referrals.
Volume of published content is not a success metric on its own, cited, sourced, and structurally sound content is.
Use the checkpoints and structural requirements from earlier as your audit sheet. Score your current pipeline on each check, note where rework clusters, then match the gaps to the operating model tier that fits your headcount and publish target. If you move to assisted or fully-automated drafting, keep the same verification bar as manual review (source check, fact density check, structure check) or the cadence gain erodes the trust gain you need for citations.
The working test is simple: if after 60 days your articles pass checks at rate, carry higher source density, and show growing citation presence and organic qualification without paid lift, the operation is working. If not, fix the verification step before buying more production capacity.
Keep manual for high-stakes thought leadership, original research, or pieces where point of view is the product. Use automated tiers for steady educational content where sourcing rules and structure can be enforced and a human still holds veto before publish. That split protects quality while gaining throughput.
Park it in a backlog with the missing evidence noted, rather than drafting anyway. Revisit only when you can attach a question cluster or search demand plus a distinct angle not covered by current top sources. This prevents review debt from speculative drafts.
Create a written style sheet with banned phrases, approved terminology, and tone examples scored 1 to 3. Run an automated check for those lists first, then have a human reviewer log changes instead of just approving. The log becomes training data for the next draft cycle.
Yes, most teams do. Assign model by content type and risk, not by team preference, and keep the same verification bar for all three. As noted in analyses of automated content creation as a spectrum, not a switch, the middle is where most scaling teams actually operate.
Remove or replace the claim immediately and record why it failed, whether date mismatch, authority mismatch, or missing primary source. Acceptable replacements are primary documents, official data, or peer-reviewed work, since vendor blogs can add context but cannot carry a statistic alone. Tracking failures shows where prompts or source lists need fixing.
Treat updates as a gated stage with its own checkpoint: updated date stamp, changelog note, and re-verification of any changed numbers. Confirm that meta, alt text, and live citations still render and that no broken domains slipped in. This keeps the asset traceable for future citation.
Assign a single human owner who holds veto power and confirms slug, canonical, and citation rendering before anything goes live. HarperFlow documents a similar pattern where the system automates research, drafting, formatting, and publishing to Webflow while retaining human review and veto. One accountable reviewer prevents auto-push errors and preserves audit trails.
Adobe found creatives spend roughly 70% of time on file management, tracking feedback, and follow-ups rather than creative work. Explicit checkpoints and built-in approvals reduce that overhead by making pass/fail visible instead of debated. Measure time saved in the checkpoint log, not just output count.